Analysis of unstructured documents with "Unstructured"
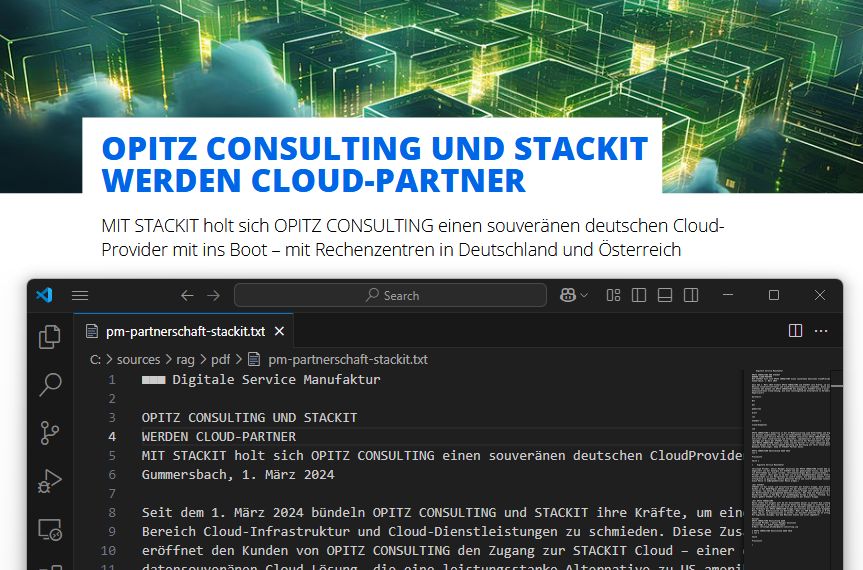
Within this test, the open-source framework unstructured is used to evaluate the extraction process of text from structured documents. The goal is to assess how suitable unstructured is for practical use in AI-based information systems – especially with respect to text extraction, semantic preparation (chunking/tokenization) and subsequent embedding generation for vector-based retrieval systems. Here is an example of a PDF file that was used for analysis with unstructured. pm-partnerschaft-stackitDownload To run the unstructured library, the official Docker image is used. It contains all required dependencies (e.g. Tesseract, Poppler, Python libraries) and allows immediate use without a local Python installation. ...